Abel Yagubyan
AI Researcher & Founder
Hello! I'm an AI researcher and founder working on trustworthy AI evaluation: the reliability of LLM-as-a-judge scoring and the reproducibility of LLM agents. I'm a Ph.D. student in Artificial Intelligence at the University of Georgia (since August 2026), and I hold an M.S. in Computer Science from Northwestern University (Summa Cum Laude) and dual B.A. degrees in Computer Science & Applied Mathematics from UC Berkeley.
I'm currently building LearnOS, an open-source, agentic AI university. I contribute to open-source LLM evaluation as an Area Triager on Snowflake's TruLens and a contributor to the UK AI Security Institute's inspect_evals, and I've completed 200+ peer reviews across nine Elsevier AI journals. I was accepted into Y Combinator's Spring 2026 batch. Earlier, I spent two years as a Senior Data Scientist at C3.ai; co-founded FibonAI (UC Berkeley SkyDeck); researched UPC++ performance at Lawrence Berkeley National Laboratory; and interned at Apple.
News
Research & Publications
How Consistent Are LLM Agents? Measuring Behavioral Reproducibility in Multi-Step Tool-Calling Pipelines
UPC++ Performance Regression Testing & Benchmarking
SCALPEL: Customized Deep Neural Network Compression
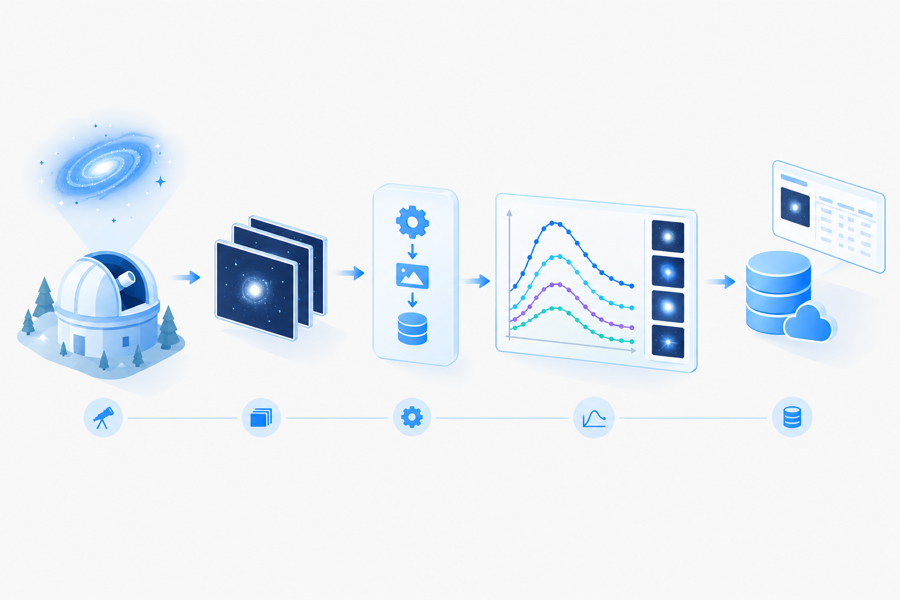
The Lick Observatory Supernova Search follow-up program: photometry data release of 70 SESNe
Seamless Embedding of Programming IDEs into Computer-Based Testing Software
Industry Experience
C3.ai
FibonAI
Apple x UC Berkeley
Software & Projects
Open Source
LearnOS
TruLens
Jury.repeated with reliability metadata on every Jury result (#2854), repeated-trial LLM-as-a-judge scoring based on the Coin Flip Judge paper, listed under New features in the 2.16.0 release. The other merged work fixes OpenTelemetry and async instrumentation, the database and persistence layer, the evaluation API, batch evaluation, providers, and the dashboard. Filed 22 issues, each closed by one of these PRs, and posted 16 reviews of other contributors' PRs, including catches of a core-only install crash and of a failing certification check in the 2.16.0 release PR before it shipped. 12th of 124 contributors by commits to main. Listed in MAINTAINERS.md with scope over OpenTelemetry instrumentation, evaluation and database correctness, and shared core code.
inspect_evals
aggregate() (#2317), moving the unscored-sample signal to the first-class Score.reason field across 9 evals (#2459), and fixing makemesay's four rate metrics, which miscounted games whose repeated trials ended differently (#2547), plus a one-line README fix. The repo's BEST_PRACTICES.md cites #2547 and #2317 as reference examples, and maintainers named #2547 when building a shared test helper for epoch-reduced metrics (#2597, #2641).
Awards & Recognition
GroundLM 2026 (EMNLP 2026)
"The Coin Flip Judge?" accepted as an Archival Long Paper.
Y Combinator
Accepted into Y Combinator's Spring 2026 batch.
Summa Cum Laude
Graduated with Summa Cum Laude honors from the M.S. in Computer Science program.
Elsevier Recognised Reviewer Certificates
- Engineering Applications of Artificial Intelligence109
- Image and Vision Computing33
- Neural Networks26
- Information Fusion18
- Neurocomputing3
- Expert Systems with Applications1
- Knowledge-Based Systems1
- Data and Knowledge Engineering1
- International Journal of Intelligent Networks1